
Bulk scraping in the browser
Scrape a list of similar URLs in one run, such as every product page in a catalogue or every job description on a job board: add your URLs and Simplescraper scrapes the same fields from each page. It runs in your browser, so pages behind your login work too.
Need to collect the URLs first?
If you need to scrape the list of URLs first, see the Sub-page (deep) scraping guide: it covers scraping a list of URLs, then running them through a bulk scrape.
For scheduled or background bulk scraping, see Bulk scraping in the cloud.
Pick the fields to scrape
Open one of the pages in your list, such as one job description. The values you click on it become the columns for every page in the list.
While on that page:
Open the extension and click 'Single fields'.
Click each value you want on the page, such as the job title, location and description. Each one appears in the panel as a field. Then click 'Continue'.
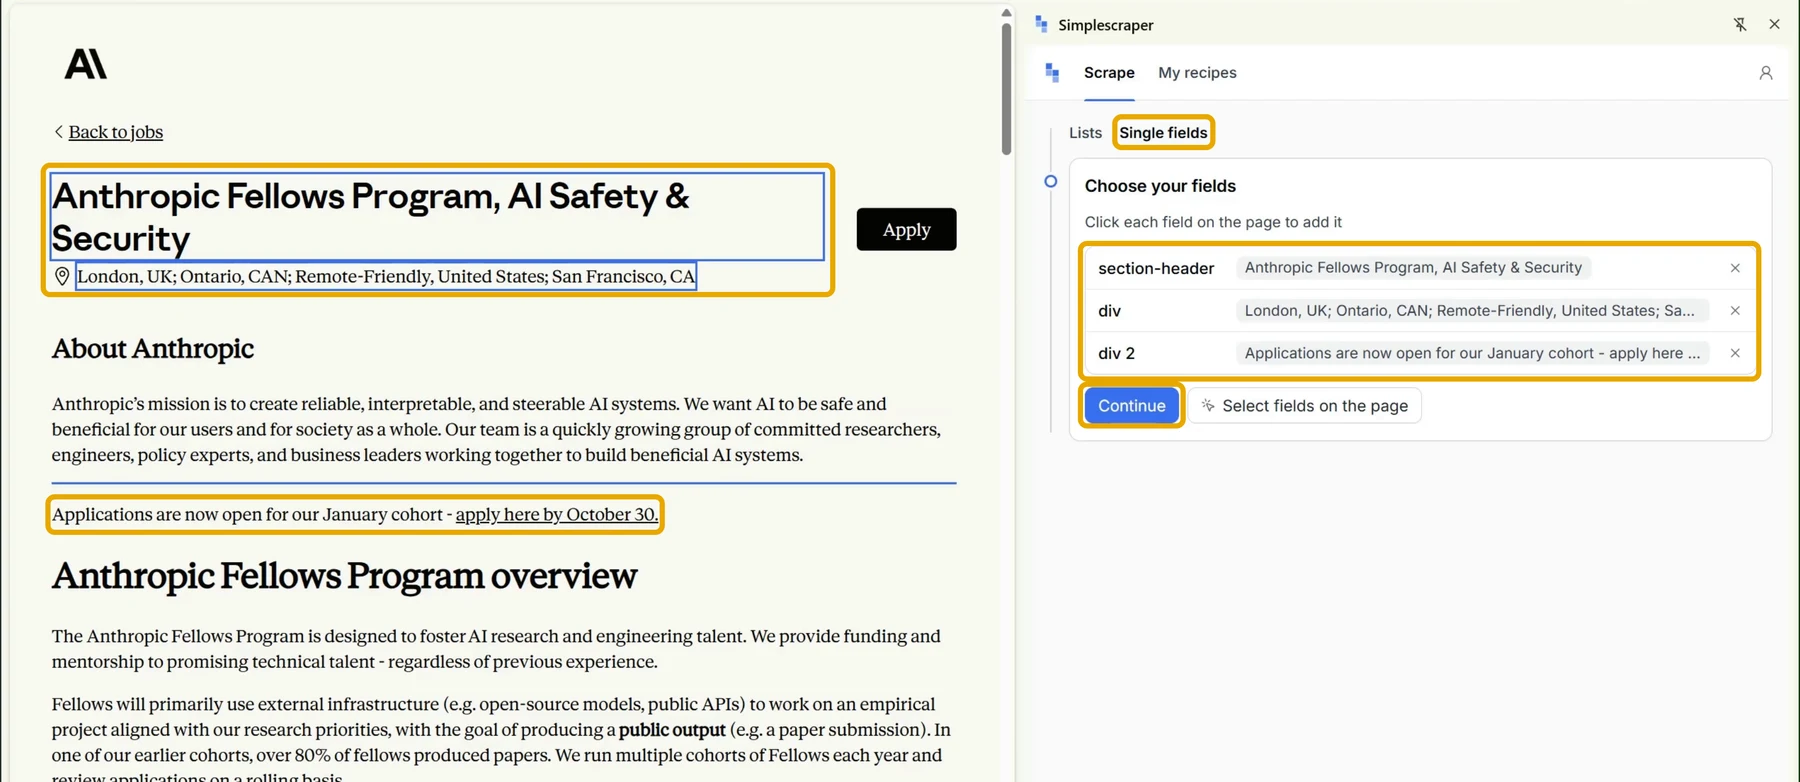
Check the field names, or click 'AI rename' for clearer ones, then click 'Continue'.
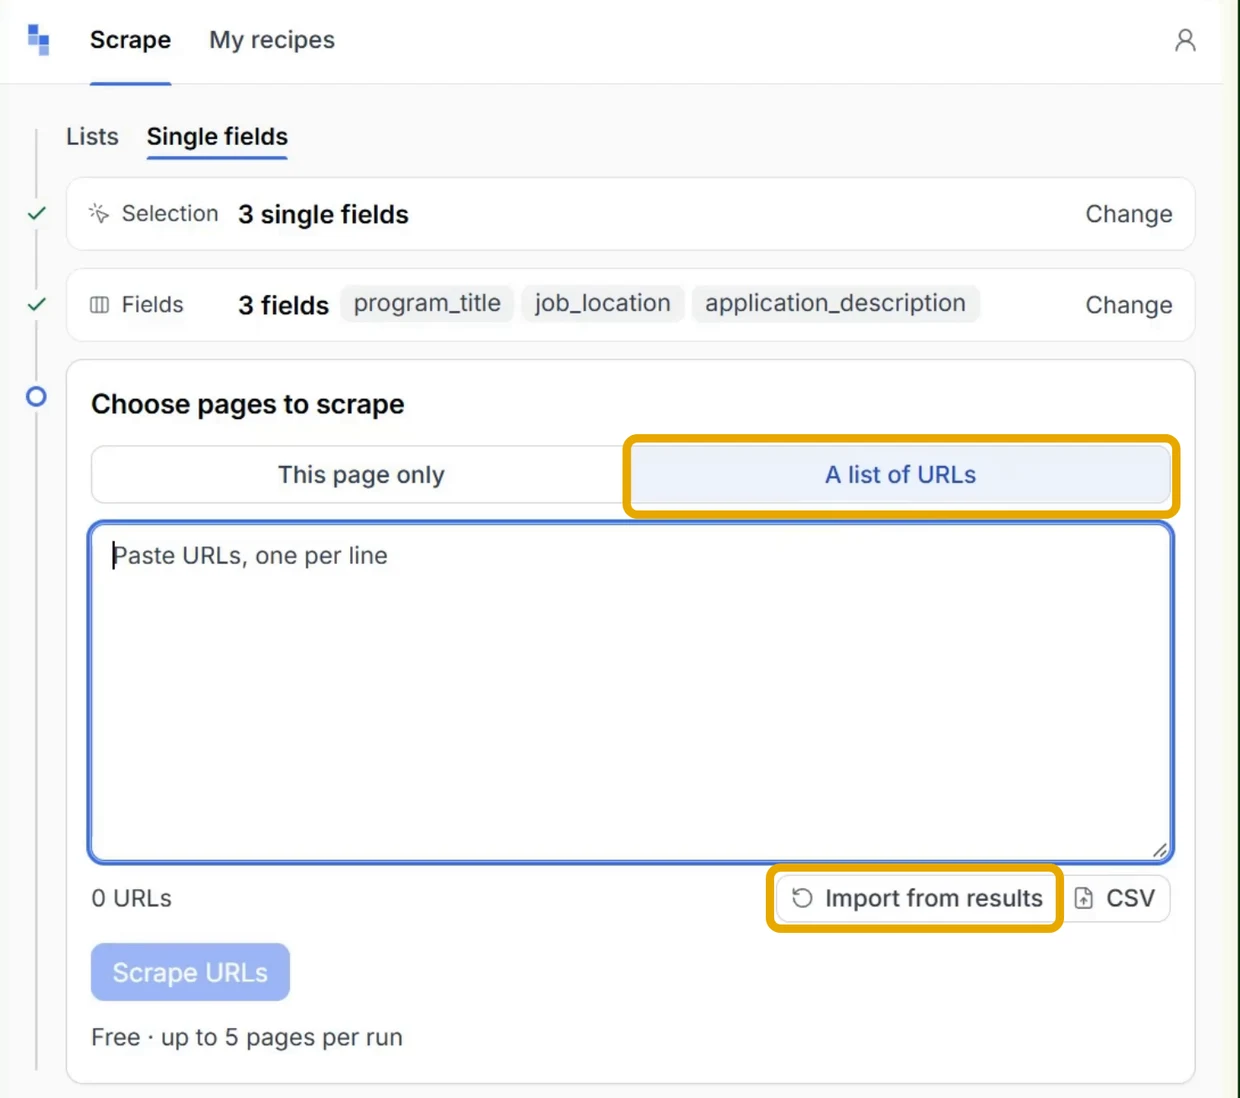
Under 'Choose pages to scrape', choose 'A list of URLs'.
Add the URLs
Add the URLs in any of three ways.
- Paste: paste them into the box, one per line. The counter shows how many URLs it found and skips anything that is not a web address.
- CSV: click 'CSV' and choose a file. Every web address in the file is added.
- Import from results: click 'Import from results', pick the scrape that collected the links under 'Run' and, if it has more than one column of links, one under 'Links column'. Then click 'Add URLs'.
Run the list
Click 'Scrape URLs'. The extension visits each address in turn in the current tab.
For a recipe that uses 'Load more' or 'Scroll', tick 'Navigate N pages on each URL' to page through each address the way the recipe does on its start page. Unticked, it scrapes only the page at each URL.
Download results
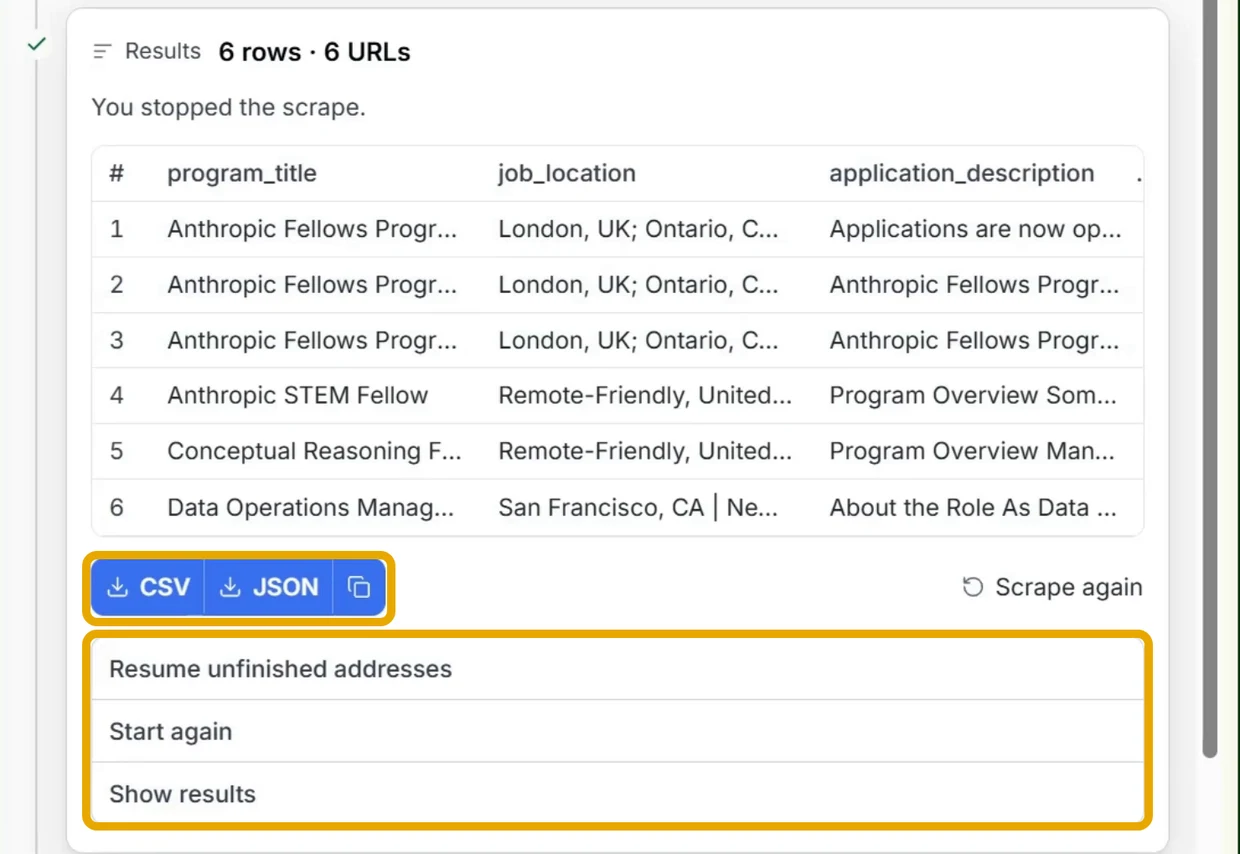
- Download: click 'CSV' or 'JSON', or the copy button to copy the rows.
- A stopped run: choose 'Resume unfinished addresses', 'Start again' or 'Show results'.
- Earlier runs of a saved recipe: open the recipe's '⋯' menu and click 'Run history'. Each run downloads as a CSV with a 'Page URL' column.
More Guides
- Sub-page (deep) scraping - scrape a list of links, then every page they lead to
- Scrape and save recipes - scrape a page and save it as a recipe
- Bulk scraping in the cloud - run a list on a schedule or with your browser closed
For questions or help, reach out via chat.